
...all the intelligent design advocates die; settles that debate, I believe.
Basically, a subtype in directshow communicates the type of media that a filter outputs, so these types let connecting filters know that a filter outputs some variant of H.264. However, both of these types are--to differing degrees--nonsensical. Microsoft could have done a better job defining these types.
For AVC1, the actual sample data is prefixed with the length in big-endian format, which is completely redundant with DirectShow's IMediaSample implementation. IMediaSample already implements GetActualDataLength() to communicate the length of the buffer, so this additional data in the sample buffer is completely unnecessary and one source of error when writing a filter. You often see code that resembles:
IMediaSample pSample;
BYTE* pBuffer;
pSample->GetPointer(&pBuffer);
DoSomethingWithMyH264Data(pBuffer + 4,pSample->GetActualDataLength - 4));
The only possible benefit I can see to prefixing the length is it makes it easy to convert back to a type with the NALU start codes (0x00000001 can simply overwrite a 4-byte start size, for example, and voila: start codes), but that's really not a big deal.
The good thing about AVC1 is that the subtype defines a single NALU per sample buffer, which is great, because at least it makes this type somewhat compatible with the DirectShow architecture. Also good is the SPS/PPS info is communicated during pin negotiation, which is helpful when determining if your decoder is capable of handling the incoming H.264 video. (e.g. in the event of video a decoder cannot handle, you can not allow a pin connection in the first place instead of having to actually parse incoming video. Transform filters don't have to wait for SPS/PPS info to lumber along, which does not necessarily happen. And so on.)
I wouldn't say AVC1 is bad; I'd reserve that designation for the certifiably stupid H264 subtypes. The H264 subtypes define a raw H264 byte stream, which means they deliver NALUs delimited with the NALU start code (0x00000001 or 0x000001). Since the H264 subtypes do not specify one NALU per buffer, I assume this means a filter can potentially deliver multiple NALU per IMediaSample. People on the newsgroups even interpet this subtype to mean that "NALU boundaries don't even have to respect the sample boundaries," which means you could get a sample that didn't contain an entire NALU, or a sample that contained half of a NALU, and so on.
But this behavior is completely nonsensical from a timestamping perspective. Each IMediaSample has a timestamp, so this model effectively makes it impossible for a downstream filter to correctly timestamp incoming H.264, which really only makes this subtype feasible for live streaming, and you can pretty much forget about syncing with audio in any meaningful way.
Needless to say, this completely violates the IMediaSample abstraction. GetActualDataLength() is wrong in the same way AVC1 is wrong (the NALU start codes are present in the buffer), but so is GetMediaTime (time for which sample???), IsSyncPoint (precisely what NALU is a sync point?), IsDiscontinuity, etc. Of course, if you decide to make a filter that outputs the H264 subtype, you can always make it output a single NALU per IMediaSample buffer, but it doesn't change the fact that filters which accept H264 subtypes cannot depend on an IMediaSample being a discrete NALU, which makes interpreting the IMediaSample data problematic.
Furthermore, in the H264 subtypes, the SPS/PPS info is not communicated in the media format exchange, which means downstream filters cannot prepare their decoder until they have parsed incoming data and located the SPS/PPS info. This simply makes no sense. All proper RTP H.264 streams should communicate SPS/PPS info in the SDP exchange, and the info is shuffled away in the MP4 format because of how important it is for decoders to be able to quickly access it so decoding can begin immediately. To not have this info up front makes it far more difficult (although not impossible, by any means) to write a filter, and there is rarely a good reason to not provide it.
In any event, my advice: avoid the H264 subtypes, they are ridiculous and only make your filter a pain in the ass to deal with. The AVC1 format is better, but it could be improved by removing the superfluous size field from the media buffer.
The following list shows the behavior of different lengths for the searchPattern parameter:
* "*.abc" returns files having an extension of .abc, .abcd, .abcde, .abcdef, and so on.
* "*.abcd" returns only files having an extension of .abcd.
* "*.abcde" returns only files having an extension of .abcde.
* "*.abcdef" returns only files having an extension of .abcdef.
 pmt->cbFormat = sizeof(WAVEFORMATEX);
 WAVEFORMATEX *wfex = (WAVEFORMATEX*)pmt->AllocFormatBuffer(sizeof(WAVEFORMATEX));
// allocate length bytes for the format and return a read/write pointer
// If we cannot allocate the new block of memory we return NULL leaving
// the original block of memory untouched (as does ReallocFormatBuffer)
BYTE*
CMediaType::AllocFormatBuffer(ULONG length)
{
    ASSERT(length);

    // do the types have the same buffer size

    if (cbFormat == length) {
        return pbFormat;
    }

    // allocate the new format buffer

    BYTE *pNewFormat = (PBYTE)CoTaskMemAlloc(length);
    if (pNewFormat == NULL) {
        if (length <= cbFormat) return pbFormat; //reuse the old block anyway.
        return NULL;
    }

    // delete the old format

    if (cbFormat != 0) {
        ASSERT(pbFormat);
        CoTaskMemFree((PVOID)pbFormat);
    }

    cbFormat = length;
    pbFormat = pNewFormat;
    return pbFormat;
}
    if (pbFormat != NULL && cbFormat == length) {
        return pbFormat;
    }
// allocate length bytes for the format and return a read/write pointer
// If we cannot allocate the new block of memory we return NULL leaving
// the original block of memory untouched (as does ReallocFormatBuffer)
BYTE*
CMediaType::AllocFormatBuffer(ULONG length)
{
    ASSERT(length);

    // do the types have the same buffer size, _and_
    // do we have a valid pbFormat pointer???
    if (pbFormat != NULL && cbFormat == length) {
        return pbFormat;
    }

    // allocate the new format buffer
    BYTE *pNewFormat = (PBYTE)CoTaskMemAlloc(length);
    if (pNewFormat == NULL) {
        // If the current pbFormat works, reuse it.  Otherwise, fail.
        return (pbFormat != NULL && length <= cbFormat) ?
            pbFormat : NULL;
    }

    // delete the old format
    if (pbFormat != NULL && cbFormat != 0) {
        CoTaskMemFree((PVOID)pbFormat);
    }

    cbFormat = length;
    pbFormat = pNewFormat;
    return pbFormat;
}
For an entire industry that defines itself based on the word "quality", today there is still no agreed upon standard for what classifies HD quality video on the web....If the industry wants to progress with HD quality video, we're going to have to agree on a standard - and fast.He's absolutely right. Many companies attempt to pass off 480p as HD video, but most video enthusiasts would reject such an assertion--after all, if it isn't HD for an analog signal, why would it be HD for a digital signal? Likewise, lots of video is encoded at an unacceptably low bit rate which results in obvious artifacts. Why would such poor quality video be considered "high definition?"
High-definition television (or HDTV) is a digital television broadcasting system with higher resolution than traditional television systems (standard-definition TV, or SDTV). HDTV is digitally broadcast; the earliest implementations used analog broadcasting, but today digital television (DTV) signals are used, requiring less bandwidth due to digital video compression.This is still lacking. What exactly is "higher resolution than traditional television systems?" And just what SDTV system, since there were many of them? And is resolution all there is to it? What if I encode video to 1080p but at a horrible bit rate, which causes lots of blocking artifacts? What about video with an odd aspect ratio, where the number of verticals lines doesn't pass muster? Clearly this definition is lacking.
Hassan Wharton-Ali brought up another good point on the thread - HD should actually be HD quality. It can’t be a lousy, over-quantized encode using a suboptimally high resolution just so it can be called HD.
A good test is the video should look worse (due to less detail), not better (due to less artifacts), if encoded at a lower resolution at the same data rate. If reducing your frame size makes the video look better when scaled to the same size, then the frame size is too high!
It is a good point, and I don't completely disagree with Ben's proposal--it should look worse due to less detail if encoded at a lower resolution. But this is the crux of the issue: what does it mean to look worse? Is this just a subjective judgment call on behalf of the person encoding the video? I don't think this addresses the problem of having a minimum acceptable "quality" for HD video.
Dan Rayburn's suggestion is even less desirable, in my opinion:
To me, the term HD should refer to and be defined by the resolution and a minimum bitrate requirement. Since you could have a 1080p HD video encoded at a very low bitrate, which could result in a poor viewing experience inferior to that of a higher-bitrate video in SD resolution, the resolution and bitrate is the only way to define HD.
The first issue with this is the "minimum bit rate" requirement would have to somehow scale with the resolution and frame rate. It would have to account for the codec being used. This would result in an impossibly complicated system, endless arguments, etc. (for example, would we impose the same bit rate requirement on H.264 as we would on VC1? What about "future" codecs?)
A bigger issue is not all video content is the same. The resulting "quality" of a video encoded to a given bitrate absolutely has a relationship with the video being encoded. A video with very little movement can often be encoded with a low bit rate and look fantastic, so the bit rate requirement would essentially amount to wasted bandwidth. Conversely, a video with a lot of motion and scene changes may require a lot more bits to get an acceptable, block-free viewing experience--and it's not clear what that acceptable threshold would be.
I find both of these suggestions insufficient. I propose an alternative: objective video quality algorithms. The idea is straight-forward: by comparing the source material with the output material, we can objectively establish a score that at least has some meaningful relationship with Mean Opinion Scores. In a nutshell, a MOS is how "good" the average person thinks some piece of video appears.
Peak Signal-to-Noise/Mean Squared Error is the most common algorithm, albeit one that is quite crude, widely considered to be deficient by most engineers and scientists. But it's 2009, baby--we can do better. We have better.
My suggestion would be the Structural SIMilarity Index, which is relatively inexpensive (its closely related brother, MSSIM, is much more pricey) and definitely correlates better with MOS.
How would this work?

I don't really care what objective metric is used, and certainly there is plenty of debate over which objective method correlates best with MOS, and what threshold should be used--but let's at least be scientific about this. If there's going to be a "standard" for High Quality video, then let's choose a standard that will carry us forward and not create a quagmire.
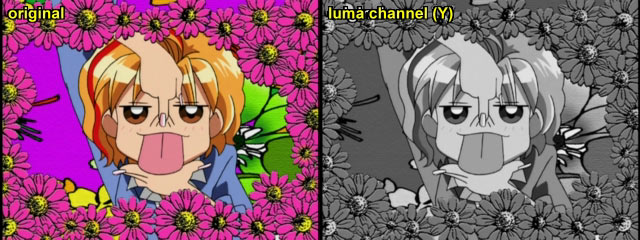
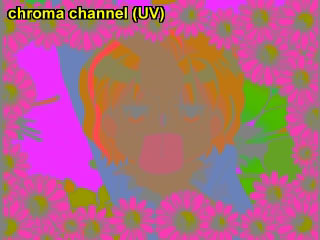
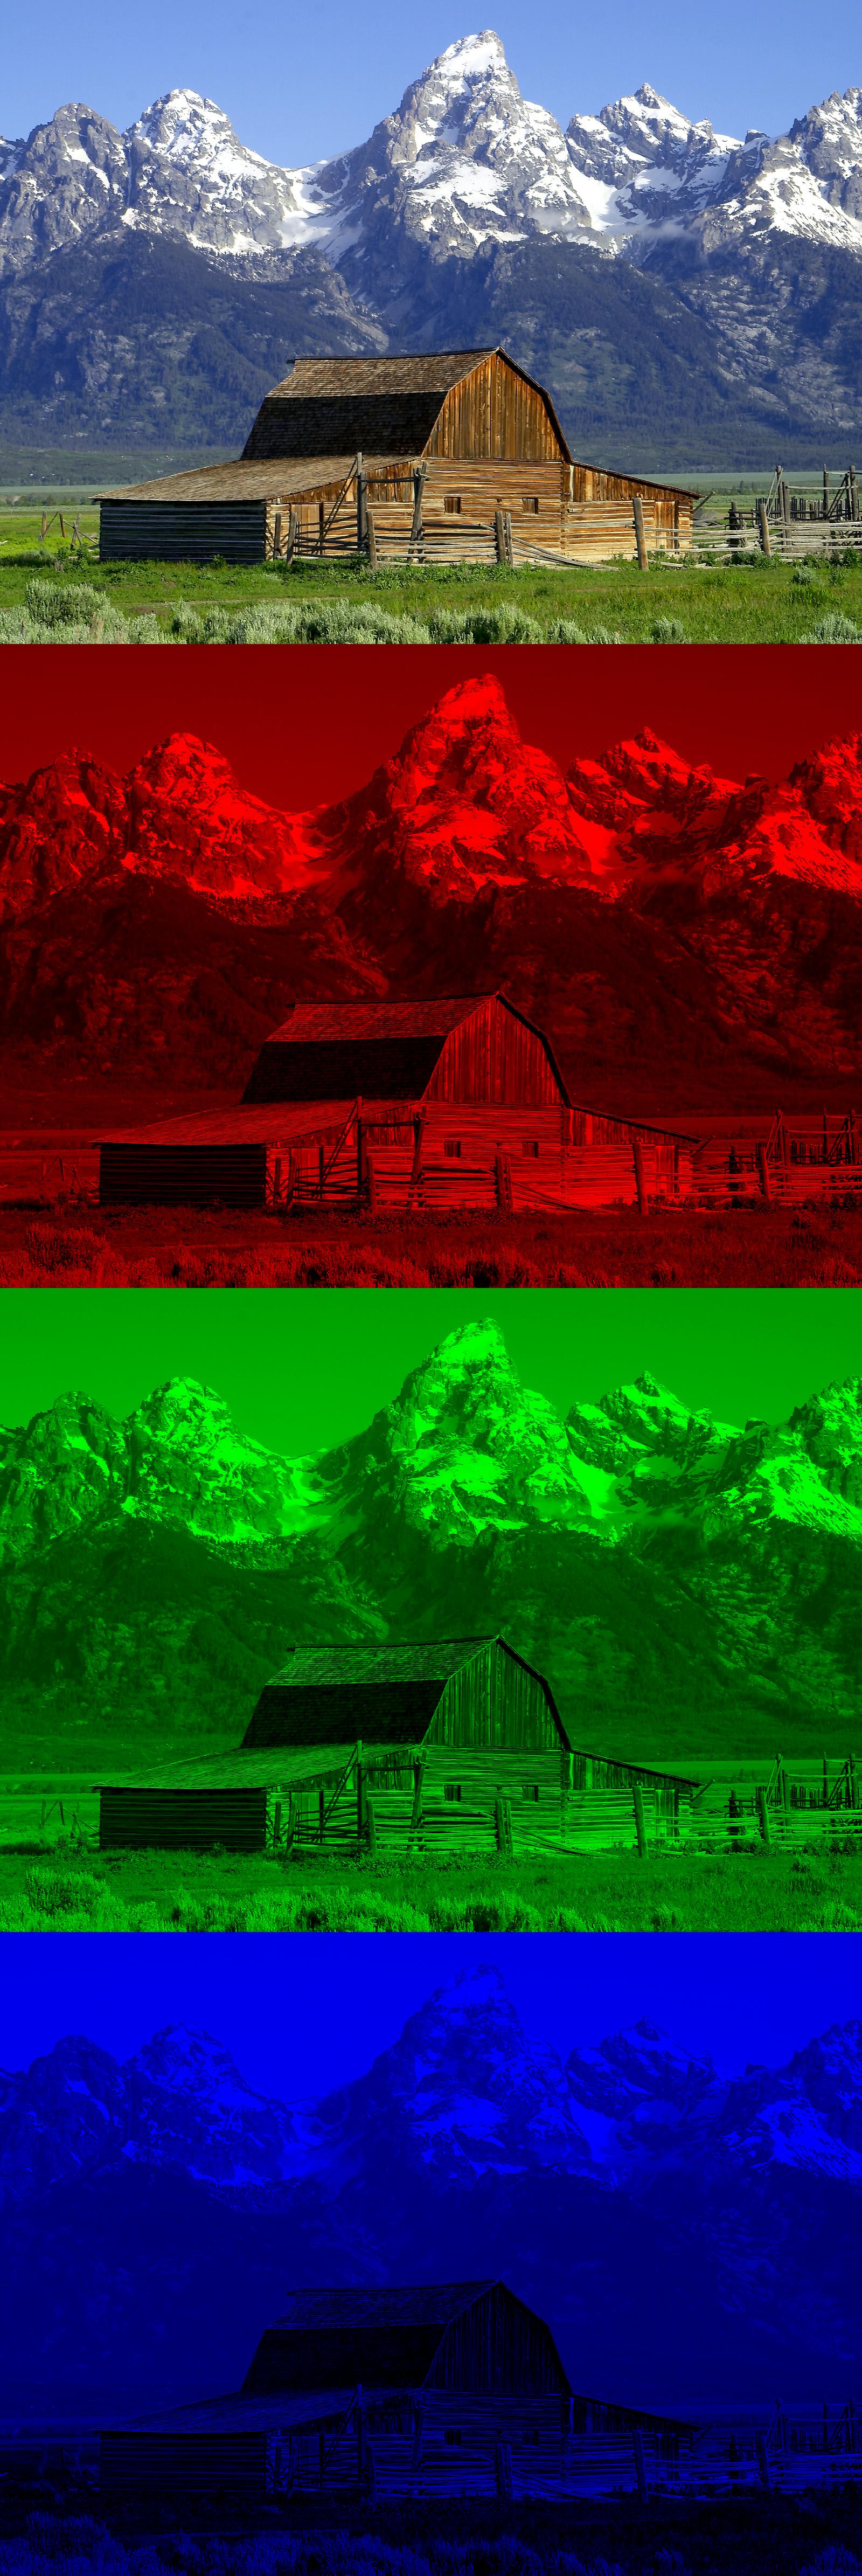 The top image of the barn is what you see. Each of the three pictures below are the red, green and blue components, respectively. When you add them together, voila, you get barnyard goodness. (sidenote: because you "add" colors together in the RGB colorspace, we call this an "additive" color model)


// Converts an image from YUY2 to AYUV.  Input and output images must
// be of identical size.  Function does not deal with any potential stride
// issues.
HRESULT ConvertYUY2ToAYUV( char * pYUY2Buffer, char * pAYUVBuffer, int IMAGEHEIGHT, int IMAGEWIDTH )
{
    if( pYUY2Buffer == NULL || pAYUVBuffer == NULL || IMAGEHEIGHT < 2
        || IMAGEWIDTH < 2 )
    {
        return E_INVALIDARG;
    }

    char * pSource = pYUY2Buffer;  // Note: this buffer will be w * h * 2 bytes (16 bpp)
    char * pDest = pAYUVBuffer;  // note: this buffer will be w * h * 4 bytes (32 bpp)
    char Y0, U0, Y1, V0;    // these are going to be our YUY2 values

    for( int rows = 0; rows < IMAGEHEIGHT; rows++ )
    {
        for( int columns = 0; columns < (IMAGEWIDTH / 2); columns++ )
        {
            // we'll copy two pixels at a time, since it's easier to deal with that way.
            Y0 = *pSource;
            pSource++;
            U0 = *pSource;
            pSource++;
            Y1 = *pSource;
            pSource++;
            V0 = *pSource;
            pSource++;

            // So, we have the first two pixels--because the U and V values are subsampled, we *reuse* them when converting
            // to 32 bpp.
            // First pixel
            *pDest = V0;
            pDest++;
            *pDest = U0;
            pDest++;
            *pDest = Y0;
            pDest += 2; // NOTE: not sure if you have to put in a value for the alpha channel--we'll just skip over it.

            // Second pixel
            *pDest = V0;
            pDest++;
            *pDest = U0;
            pDest++;
            *pDest = Y1;
            pDest += 2; // NOTE: not sure if you have to put in a value for the alpha channel--we'll just skip over it.
        }
    }

    return S_OK;
}
// Converts an image from YV12 to YUY2.  Input and output images must
// be of identical size.  Function does not deal with any potential stride
// issues.
HRESULT ConvertYV12ToYUY2( char * pYV12Buffer, char * pYUY2Buffer, int IMAGEHEIGHT, int IMAGEWIDTH )
{
    if( pYUY2Buffer == NULL || pYV12Buffer == NULL || IMAGEHEIGHT < 2
        || IMAGEWIDTH < 2 )
    {
        return E_INVALIDARG;
    }

    // Let's start out by getting pointers to the individual planes in our
    // YV12 image.  Note that the Y plane in a YV12 image's size is
    // simply the image height * image width.  This is because all values
    // are 8 bits.  Also notice that the U and V planes are one quarter
    // the size of the Y plane (hence the division by 4).
    BYTE * pYV12YPlane = pYV12Buffer;
    BYTE * pYV12VPlane = pYV12YPlane + ( IMAGEHEIGHT  * IMAGEWIDTH );
    BYTE * pYV12UPlane = pYV12VPlane + ( ( IMAGEHEIGHT  * IMAGEWIDTH )  / 4 );

    BYTE * pYUV2BufferCursor = pYUV2Buffer;

    // Keep in mind that YV12 has only half of the U and V information that
    // a YUY2 image contains.  Because of that, we need to reuse the U and
    // V plane values, so we only increment that buffer every other row
    // of pixels.
    bool bMustIncrementUVPlanes = false;

    for( int ImageHeight = 0; ImageHeight < IMAGEHEIGHT; ImageHeight++ )
    {
        // Two temporary cursors for our U and V planes, which are the weird ones to deal with.
        BYTE * pUCursor = pYV12UPlane;
        BYTE * pVCursor = pYV12VPlane;

        // We process two pixels per pass through this equation,
        // hence the (IMAGEWIDTH/2).
        for( int ImageWidth = 0; ImageWidth < ( IMAGEWIDTH / 2 ) ; ImageWidth++ )
        {
            // first things first: copy our Y0 value.
            *pYUY2BufferCursor = *pYV12YPlane;
            pYUY2BufferCursor++;
            pYV12YPlane++;

            // Copy U0 value
            *pYUY2BufferCursor = *pUCursor;
            pYUY2BufferCursor++;
            pUCursor++;

            // Copy Y1 value
            *pYUY2BufferCursor = *pYV12YPlane;
            pYUY2BufferCursor++;
            pYV12YPlane++;

            // Copy V0 value
            *pYUY2BufferCursor = *pVCursor;
            pYUY2BufferCursor++;
            pVCursor++;
        }

        // Since YV12 has half the UV data that YUY2 has, we reuse these
        // values--so we only increment these planes every other pass
        // through.
        if( bMustIncrementUVPlanes )
        {
            pYV12VPlane += IMAGEWIDTH / 2;
            pYV12UPlane += IMAGEWIDTH  / 2;
            bMustIncrementUVPlanes = false;
        }
        else
        {
            bMustIncrementUVPlanes = true;
        }
    }

    return S_OK;
}

 Unfortunately, this service is also in control of a whole host of junk, so stopping the service results in your wireless connection dying. For a while, it seemed like there may be some love in registry key HKEY_LOCAL_MACHINE\SOFTWARE\Microsoft\Wlansvc\Interfaces\INTERFACE_NAME\ScanInterval, which is set to 60 EA 00 00 (EA60 is 60000 in hex, which is the number of milliseconds that elapse between each lag spike), but the Scan Interval field is simply overwritten every time the WLAN Autoconfig service is started with good ol' EA 60. (side rant: why bother putting a value in the registry if the service is simply going to overwrite it every time it starts??? Is this quality of code really worth paying several hundred dollars for?)


